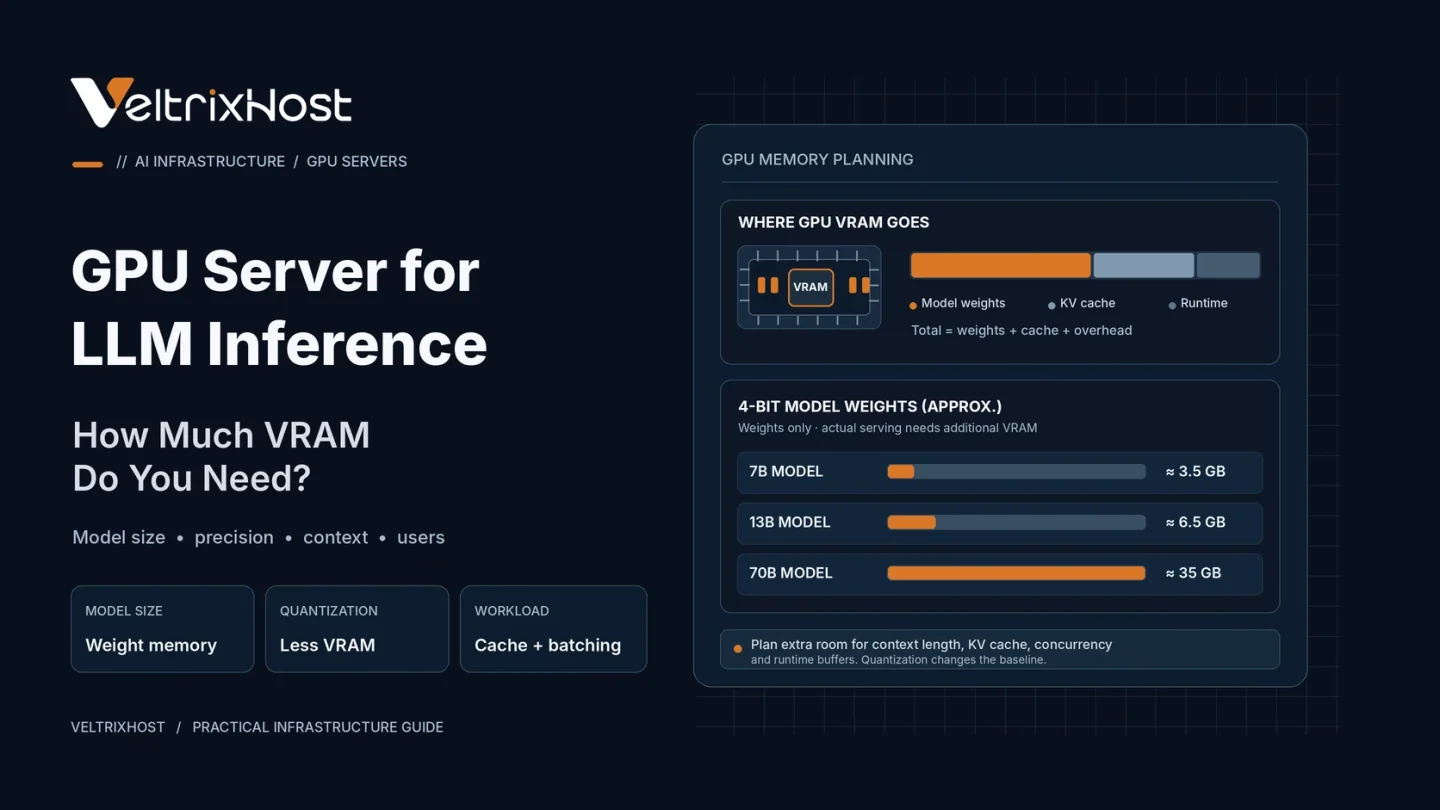
Choosing a GPU server for LLM inference starts with understanding VRAM requirements. Large language models need GPU memory for model weights, attention caches, and temporary processing operations.
However, buying the GPU with the most VRAM is not always necessary. The right configuration depends on model size, quantization, context length, and concurrent users.
Why Does VRAM Matter for LLM Inference?
VRAM is the dedicated memory available to a graphics processor.
During inference, the GPU stores model parameters and intermediate data required to generate responses.
If memory becomes insufficient, the model may fail to load or require CPU offloading. Offloading can reduce GPU memory requirements but may increase response times.
Therefore, VRAM capacity directly affects which models and workloads your server can support.
How Much VRAM Does an LLM Need?
Model size and numerical precision determine the approximate memory required for model weights.
For example, FP16 and BF16 typically use two bytes per parameter, while 4-bit quantization reduces the theoretical weight storage requirement.
| Model size | FP16/BF16 weights | 4-bit weights |
|---|---|---|
| 7B | 14GB | 3.5GB |
| 8B | 16GB | 4GB |
| 13B | 26GB | 6.5GB |
| 32B | 64GB | 16GB |
| 70B | 140GB | 35GB |
These figures represent theoretical weight storage only. Actual deployment requires additional memory for quantization metadata, KV cache, runtime operations, and memory allocation.
What Is the KV Cache?
The key-value (KV) cache stores attention information from previously processed tokens.
Longer prompts and more simultaneous requests generally increase its memory requirements.
For example, a model serving one short conversation may consume substantially less VRAM than the same model handling many long conversations.
The exact amount depends on the model architecture and inference engine.
How Does Quantization Reduce VRAM?
Quantization stores model weights using fewer bits.
Common options include 8-bit and 4-bit formats, which can make larger models practical on smaller GPUs.
However, quantization may affect output quality, numerical accuracy, and processing performance.
Review the official Hugging Face LLM memory optimization guide for additional technical details.
Which GPU Configuration Should You Choose?
For smaller 7B–8B quantized models, GPUs with 12–24GB VRAM can be practical starting points.
Larger 32B models may benefit from 24–48GB or more, depending on precision and concurrency.
A 70B model often requires high-memory accelerators or multiple GPUs, particularly without aggressive quantization.
Before purchasing, benchmark your chosen model with realistic context lengths and simultaneous requests.
What Else Matters Besides VRAM?
GPU memory capacity is only one specification.
Also compare memory bandwidth, supported precision formats, GPU compute performance, CPU resources, system RAM, NVMe storage, and networking.
For self-managed AI deployments, explore VeltrixHost GPU Dedicated Servers and confirm accelerator availability before ordering.
Final Recommendation
A GPU server for LLM inference should provide enough VRAM for model weights, KV cache, and runtime overhead.
Start by identifying your model and precision. Then measure actual GPU memory usage, response latency, and concurrent-user capacity.
Choose hardware based on tested workload requirements rather than parameter count alone.
FAQs
Is 24GB VRAM enough for LLM inference?
Yes, for many smaller models and some larger quantized models. Context length and concurrency affect capacity.
Can a 70B model run on one GPU?
Yes, with sufficient VRAM and compatible software. Quantization can reduce its requirements significantly.
Does more VRAM make inference faster?
Not automatically. Memory bandwidth, compute performance, and model architecture also affect speed.
Can multiple GPUs share an LLM?
Yes. Compatible inference frameworks can distribute model execution across multiple GPUs.